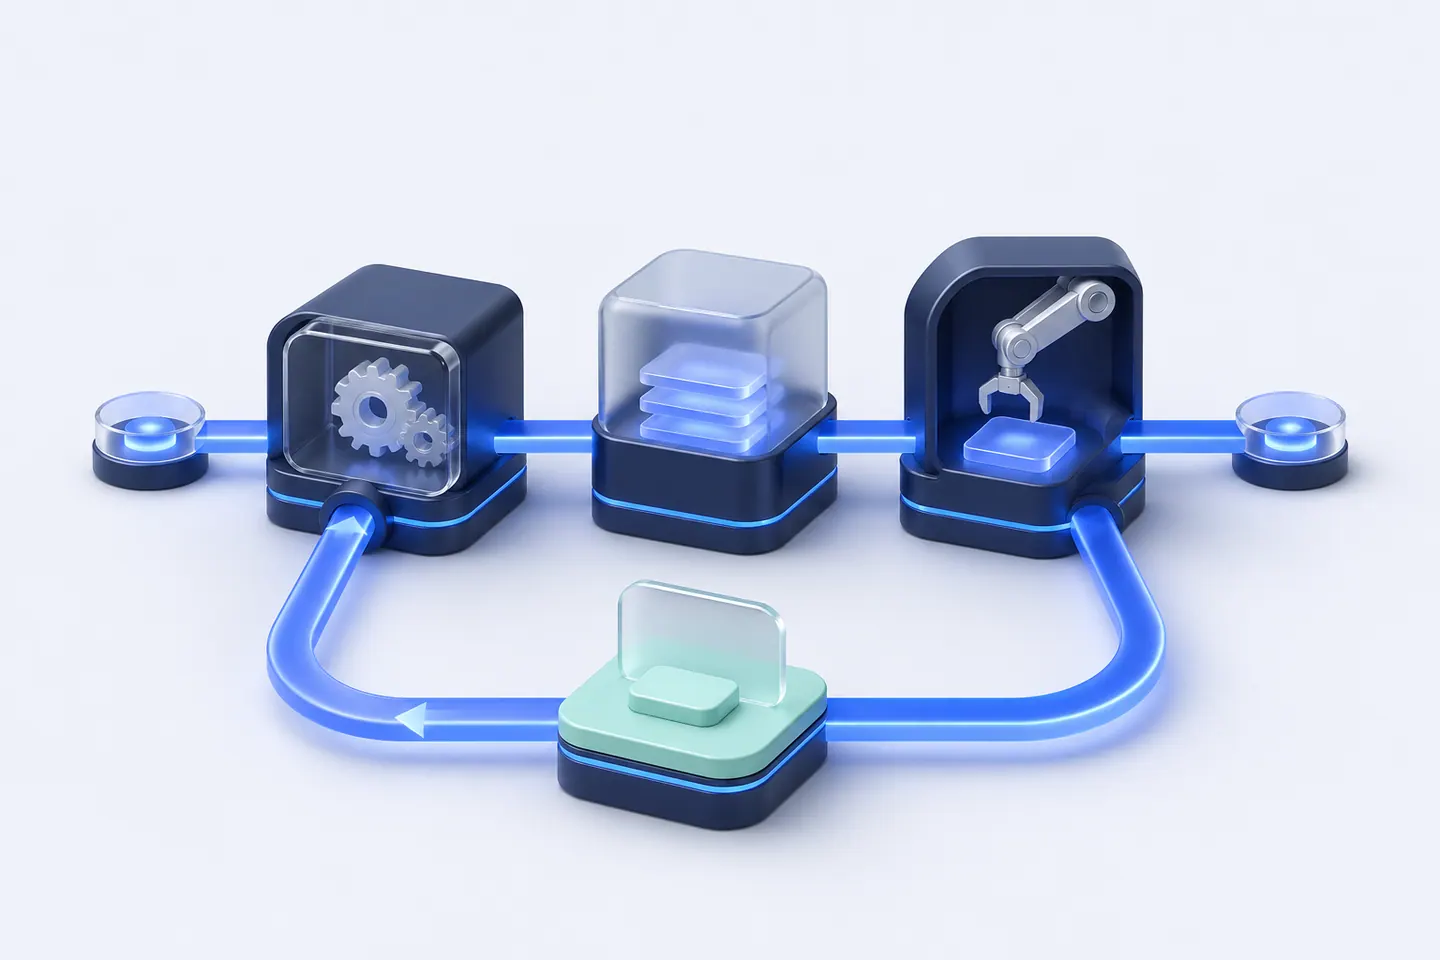
Reliable workflows need more than a happy path: clear ownership, safe retries and visible exceptions make the difference.
Describe the failure path
Every connected workflow depends on systems that can be slow or unavailable. Decide which actions can be retried safely, how to avoid duplicate records and when a person should take over.
Give exceptions somewhere to go
A failed event should create an actionable item with enough context to resolve it. Assign an owner and preserve a useful record of the original request.
Measure the work left behind
Count unresolved exceptions and repeated manual corrections as well as completed runs. The aim is a process that remains understandable when something changes.